In today’s data-driven world, more data doesn’t always mean better decisions. We often overvalue data and undervalue statistics. Excessive, poorly guided analyses, especially with high-dimensional data, risk overfitting and false discoveries. The post explains that data is meaningless without solid statistical methods and expert oversight, and cautions against trusting AI-driven statistical analyses.
AI
Big data
Biomarkers
p-values
Univariable screening
Author
Simon Schwab
Published
July 9, 2024
Where, oh, where would we researchers be without statistics? It enables us to analyze and report our study findings. Statistics add value to the data, creating information and meaning. Without statistics, data have only minimal meaning.
You can be rich in data but poor in information. —Stephen Senn
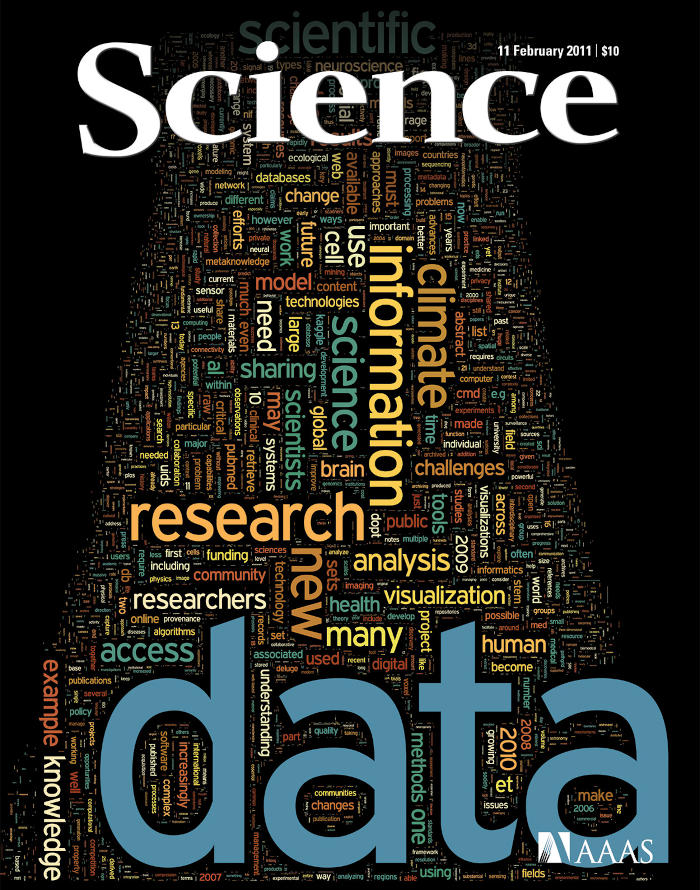
My view is that all data are rubbish without proper statistics. Nevertheless, the glorification of data has evolved over the last decades and continues to do so. An example is the front cover of the magazine Science from 2011. It is a collage of words, but only one stands out in large letters: “data.”
Science magazine front cover from 11. February 2011.
We are indeed very hungry for data. However, I don’t believe data should take center stage. What is more important is how we handle data, and how we perform statistics on the data that lead to valuable insights.
I tried to find the word “statistics” on the Science front cover but could not find it. Can you see it? Maybe the word “data” should be a bit smaller to leave more room for the word “statistics,” the discipline that concerns the collection, organization, analysis, interpretation, and presentation of data.
Nevertheless, many medical studies are conducted with little or no involvement of adequately trained statisticians, and the same is true for scientific peer review [1]. Many researchers don’t use statistics properly because they don’t know enough about it. Statisticians are often only involved at the end of a study to analyze the data despite being specialists in helping researchers clarify the question and designing the study from scratch. Often, research projects do not include enough funding for statistical work.
It feels like data is largely overvalued these days, and statistics is largely undervalued.
Big data
Another example of the glorification of data is the term Big Data. Often this refers to omics data, for example, transcriptional, epigenetic, proteomic, and metabolomic data [2].
Big data is not better than smaller data. Big data may be the price we pay for increasingly data-hungry methods from machine learning, a hyped discipline also known as artificial intelligence or simply “AI.” However, 4,000 biomarkers times 200 patients are not big data; the sample size is still N=200, and I consider this a small study. For a prediction model, for example, I would instead prefer four clinically relevant variables from 2,000 patients, even though this reflects only 1% of the data in the former example. I’m more impressed by the length of a data set (number of patients) than its width (number of variables).
Too much data can make data analysis harder, but this is often unrecognized. The unsystematic collection of high-dimensional data, when data sets are wider than they are long, can lead to more questions than answers [3]. For example, the failure of protein cancer biomarker research [4] or the failure of the Human Brain Project[5]. Learning from the past, the combination of big data and overhyped promises is a reason for concern.
There is this catchphrase “let the data speak for itself”, and I think it is misleading because data rarely have meaning without context. To extract valuable insights, you need a good question and the appropriate method to answer it.
Think about your favorite restaurant and dish: imagine being served only unprepared raw food. That’s what data are basically without a statistical analysis. Data on their own are unusable, uninterpretable, and meaningless. Data on their own are pretty dumb.
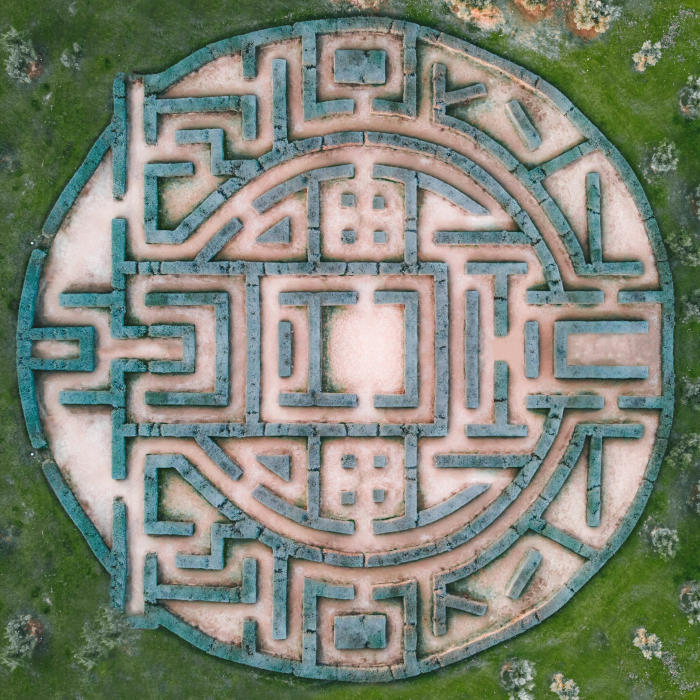
While data are dumb, more data can be even dumber. Let me explain this. You may object that more data will always lead to less uncertainty. This is, in principle, true. In reality, though, I can see lots of different ways that a large data set could be explored, analyzed, and reanalyzed until we get the result we want or until the model fits the data. Then, this process only appears to reduce the uncertainty when looking at the standard errors. More likely, the process by which the data were analyzed has increased our uncertainty, but this is often unrecognized. It is a fallacy called the garden of forking paths.
Garden of Forking Paths, Parque Juan Carlos I, Madrid, Spain. (Photo by Victor on Unsplash)
Excessive analytic attempts generate phantom degrees of freedom [6], which is one of the many ways dark statistics can deceive us. We can only trust our statistical results if we don’t torture the data too much.
Brave new tools
Statistics cooks raw data into something we can consume. However, statistical data analysis is not something that can be prepared quickly and easily like a microwave-ready meal. It requires specialist work. And yes, mistakes can be made in this process [7]. Why can’t AI do all the difficult work for us?
Researchers have always dreamed that a nice graphical interface could enable statistics at the push of a button. Instead, the opposite happened with the R programming language. We moved away from pressing buttons to writing code, which, by the way, is reproducible and verifiable. An analysis by an AI agent is not reproducible, unless the AI writes analytic R code for you. But those who will understand this code probably enjoy writing it themselves, and those who do not understand such code are unable to verify what is being served to them.
I recently discovered a website with yet another attempt to make statistics easy: an AI-powered statistics tool.
It makes complex data analytics accessible to anyone, eliminating the need for advanced technical knowledge or expertise. —from a website about an AI-based statistics tool
How does it work? I don’t know. Perhaps you can simply chat with your data files? For me, it sounds more like the production of flawed conclusions by untrained people via dangerous tools. That seems to be the gloomy future ahead of us.
Maybe AI will be terrible at being a personal statistical assistant. Maybe AI is much better at misusing statistics. It may be the perfect p-hacking machine. AI is misused in many ways to produce fake images, fake texts, fake human voices, and fake videos. Why not fake statistics? AI may become the perfect tool for data fabrication in the future. Or, as Cathy O’Neil said, a new weapon of math destruction [8]. In the future, we will need more people like Elisabeth Bik, who can spot fake research [9].
What lies ahead of us?
Nowadays, AI and machine learning are heavily promoted to “revolutionize healthcare”; this seems an overhyped claim given the notorious overfitting of data in the field [10]. To be fair, it is not just AI that baffles me. Recently, 246 biologists obtained different results from the same data [11] or the latest blunder in functional MRI research [12]. This all demonstrates that we researchers seem to learn a lot from the noise in the data.
Now, are you ready for what is next? A world where the relentless rush of technology blurs the lines between what’s real and what’s not?
A world of fake plastic trees?
The title of this post is a song by Radiohead. The preview image of this post is a photo by Frames For Your Heart on Unsplash.
Just one more thing
I performed a simulation to highlight the challenges with wide data. First, I created data with many patients but only a few variables (long data). Say, the variables have been selected as the clinically most relevant prognostic variables based on the literature and expert knowledge.
In a second step, I generated some high-dimensional data with many more variables than patients (wide data).
But first, I needed to write a short function tidy_lm() to produce a tidy output from a linear regression model; this is just cosmetics.
Code
# helper function for lm outputtidy_lm <-function(fit) { sfit =summary(fit) lower =confint(fit)[,1] upper =confint(fit)[,2] betas =coef(fit) effect =sprintf("%.2f", betas) ci =sprintf("%.2f to %.2f", lower, upper) tab =data.frame(effect = effect,ci = ci,pvalue = swt::tidy_pvalues(sfit$coefficients[,4]))colnames(tab) =c("Effect estimate", "95% CI", "p-value")return(tab)}
Long data
Code
set.seed(2024)SNR =0.65# corresponds to 20% explained variance R^2N =2000# number of patientsq =4# number of predictors# generate data for a studydata =array(rnorm(N*q), dim =c(N, q))noise =rnorm(N) # generate standard normal errorsy =0.5*data[,1] +0.3*data[,2] +0.2*data[,3] +1/sqrt(SNR)*noise
I simulated data for \(N = 2000\) patients and \(q = 4\) variables. I assumed the three prognostic variables (\(x_1\), \(x_2\), and \(x_3\)) were uncorrelated and related to the outcome using an additive model. The true effects were \(\beta_1 = 0.5\), \(\beta_2 = 0.3\), and \(\beta_3 = 0.2\). For the unrelated variable \(x_4\), we had \(\beta_4 = 0\). I added some noise so that the explained variance was about 20% (\(R^2\)). The results are shown in Table 1.
Code
d =data.frame(y = y, x1 = data[,1], x2 = data[,2], x3 = data[,3], x4 = data[,4])fit =lm(y ~ ., data = d)tidy_lm(fit)
Table 1: Results from a regression model fitted with long data using simulated data from 2000 patients.
Effect estimate
95% CI
p-value
(Intercept)
0.00
-0.05 to 0.06
0.96
x1
0.49
0.43 to 0.54
< 0.001 ***
x2
0.31
0.25 to 0.37
< 0.001 ***
x3
0.23
0.17 to 0.29
< 0.001 ***
x4
-0.01
-0.07 to 0.04
0.67
The p-values for the first three variables were statistically significant. This basically means that the data were very incompatible with our null model that the true effects were zero (my lawyers helped me with the wording of this sentence). For \(x_4\), the p-value was statistically non-significant. But there was something more interesting to see than \(p\)-values and statistical significance.
More interesting were the effect estimates. Since I was the creator of the data, I could see that the estimates were close to the true effects. For example, \(\beta_1\) was 0.5, and the estimate was 0.49. Not too bad.
Wide data
Code
set.seed(2024)SNR =0.65# corresponds to 20% explained variance R^2N =200# number of patientsq =4000# number of biomarkers# generate data for a studydata =array(rnorm(N*q), dim =c(N, q))noise =rnorm(N) # generate standard normal errorsy =0.5*data[,1] +0.3*data[,2] +0.2*data[,3] +1/sqrt(SNR)*noisepvalues =rep(NA, q)for (i in1:q) { # iterate across biomarkers d =data.frame (y = y, x = data[, i]) # univariable screening fit =lm(y ~ x, data = d) stats =summary(fit) pvalues[i] = stats$coefficients[2,4]}
Next, I increased the amount of data by a factor of 100. However, I did not increase the sample size in terms of the number of patients. Instead, I created data with \(q = 4000\) biomarkers (high-dimensional data). Since these may be expensive and complex measurements, I decreased the sample size to \(N = 200\). For each biomarker, I estimated a univariable model and used a cutoff of \(p \le 0.05\) for screening (univariable screening). I know it is a really bad idea, but since so many papers have done it, it shouldn’t hurt anyone to do it just one more time.
Let’s now pretend we knew that \(x_1\), \(x_2\), and \(x_3\) were the relevant biomarkers. The regression results from the same model as above (\(x_1\) to \(x_4\)) are shown below in Table 2.
Code
d =data.frame (y = y, x1 = data[,1], x2 = data[,2], x3 = data[,3], x4 = data[,4])fit =lm(y ~ x1 + x2 + x3 + x4, data = d)tidy_lm(fit)
Table 2: Results from a regression model fitted with wide data using simulated data from N=200 patients.
Effect estimate
95% CI
p-value
(Intercept)
-0.05
-0.21 to 0.12
0.58
x1
0.47
0.31 to 0.63
< 0.001 ***
x2
0.20
0.02 to 0.38
0.026 *
x3
0.24
0.07 to 0.41
0.005 **
x4
0.07
-0.10 to 0.24
0.41
The effect estimates were more off from the truth, particularly \(x_2\), and the confidence intervals were much wider. This was not surprising as the sample size was only \(N = 200\). All in all, we are much more uncertain; though, the p-values for \(x_1\) to \(x_3\) were still statistically significant. However, the larger uncertainty was not the main problem.
Code
k =sum(pvalues <=0.05)pvalues.adj =p.adjust(pvalues, method ="fdr")k.adj =sum(pvalues.adj <=0.05)
The main problem was that we didn’t know that \(x_1\), \(x_2\), and \(x_3\) were the relevant biomarkers in the first place. Using univariable screening, with \(p \le 0.05\) for variable selection, a striking 214 out of 4000 variables were statistically significant, which is close to what we would expect under a 5% alpha level.
I tried to adjust the p-values to control the false discovery rate (FDR) at 5% using the Benjamini & Hochberg procedure; however, only \(x_1\) remained statistically significant. So, this only partially helped. I wanted more specificity, and I had to pay with sensitivity. It seems to be really difficult to get the correct model with such a large data set. It’s like looking for a needle in a haystack.
In the final step, perhaps out of desperation, I opted for a middle way: instead of using an unadjusted threshold of 5% or an FDR of 5%, I applied an unadjusted threshold of \(p \le 0.001\). The results are shown in Table 3.
Code
idx =which(pvalues <=0.001) # select variables with arbitrary thresholdd =data.frame(y = y, x = data[, idx]) fit =lm(y ~ ., data = d)tab =tidy_lm(fit)# add variable namesrownames(tab)[2:(length(idx) +1)] =paste0("x", idx)tab
Table 3: Results from a regression model fitted with wide data and using univariable screening to find relevant biomarkers.
Effect estimate
95% CI
p-value
(Intercept)
-0.01
-0.17 to 0.14
0.86
x1
0.36
0.20 to 0.51
< 0.001 ***
x602
-0.34
-0.50 to -0.17
< 0.001 ***
x971
0.19
0.03 to 0.35
0.017 *
x2186
0.28
0.12 to 0.45
< 0.001 ***
x3748
0.14
-0.01 to 0.30
0.073 .
With this step, we have left the realm of science facts and entered the realm of science fiction. The results above show voodoo statistics with statistically significant results for the variables that are pure noise (except \(x_1\)). The model explained 28% of the variance (adj. \(R^2\)).
I think I tortured the data too much.
So what?
So what does this mean? I find the analysis of high-dimensional data extremely difficult, although some excellent training materials exist [13]. Certainly, there are situations where the problem is not so extreme, but there may be situations where the issue is even more extreme. It is almost impossible to find the relevant “truths” in the data when trying too many different things (the garden of forking paths).
You may object that the simulations I made were too pessimistic. Yes, but we often don’t know how good the signal-to-noise ratio is in clinical data. And completely in the dark, we must be very careful in the process of analyzing high-dimensional data, particularly when we use variable selection. Univariable screening is well-known for providing flawed results, but it is still widely used today (or widely misused, I should say).
The process of how the result was obtained is much more important than the result itself. Sadly, journals and reviewers often focus on the result, and not on the process of how a result was obtained.
References
1.
Van Calster B, Wynants L, Riley RD, Smeden M van, Collins GS. Methodology over metrics: Current scientific standards are a disservice to patients and society. J Clin Epidemiol. 2021;138: 219–226. doi:10.1016/j.jclinepi.2021.05.018
2.
Shilo S, Rossman H, Segal E. Axes of a revolution: Challenges and promises of big data in healthcare. Nat Med. 2020;26: 29–38. doi:10.1038/s41591-019-0727-5
Diamandis EP. The failure of protein cancer biomarkers to reach the clinic: Why, and what can be done to address the problem? BMC Med. 2012;10: 87. doi:10.1186/1741-7015-10-87
5.
Yong E. The human brain project hasn’t lived up to its promise. The Atlantic. 2019.
6.
Harrell FE. Regression modeling strategies. Springer International Publishing; 2015. doi:10.1007/978-3-319-19425-7
7.
Schwab S, Held L. Statistical programming: Small mistakes, big impacts. Significance. 2021;18: 6–7. doi:10.1111/1740-9713.01522
8.
O’Neil C. Weapons of math destruction: How big data increases inequality and threatens democracy. 1st ed. Crown; 2016.
9.
Shen H. Meet this super-spotter of duplicated images in science papers. Nature. 2020;581: 132–136. doi:10.1038/d41586-020-01363-z
10.
Volovici V, Syn NL, Ercole A, Zhao JJ, Liu N. Steps to avoid overuse and misuse of machine learning in clinical research. Nat Med. 2022;28: 1996–1999. doi:10.1038/s41591-022-01961-6
11.
Oza A. Reproducibility trial: 246 biologists get different results from same data sets. Nature. 2023;622: 677–678. doi:10.1038/d41586-023-03177-1
12.
Prillaman M. This fMRI technique promised to transform brain research - why can no one replicate it? Nature. 2024. doi:10.1038/d41586-024-00931-x